Ship It Conversations: Meta’s Francois Richard on AI Incident Response, SLOs, and Reliability at Scale

Ship It Conversations: Meta’s Francois Richard on AI Incident Response, SLOs, and Reliability at Scale

Author: Teller's Tech - DevOps, SRE and Cloud Podcast June 16, 2026 Duration: 42:56

This is a guest conversation episode of Ship It Weekly, separate from the weekly news recaps.

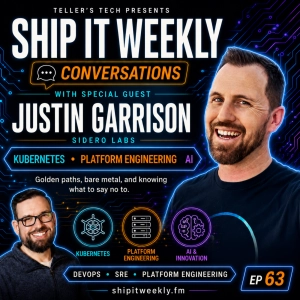
In this Ship It: Conversations episode, I talk with Francois Richard, Engineering Director at Meta, about reliability at scale, how AI is changing production risk, what teams actually learn from incidents, and why recovery practice matters just as much as prevention.

We talk about the proactive and reactive sides of reliability, why SLOs should represent a promise to users instead of just another dashboard number, how incident reviews should drive real system improvements, and how teams can practice recovery before production forces the lesson on them.

The bigger theme here is that reliability is not just about avoiding failure. It is about knowing what happens when prevention fails. That means practicing regional failure, understanding overload behavior, improving incident response, using AI carefully during investigation, and making reliability targets match the actual lifecycle and importance of the system.

Highlights

• Why reliability work starts with both prevention and recovery

• The difference between reactive incident response and proactive reliability engineering

• How Meta thinks about disaster recovery testing and regional failure practice

• Why an SLO should be treated like a promise to users, not just a dashboard metric

• How SLO trends help teams decide when to invest more in reliability or take more product risk

• What engineers actually learn during the “pressure cooker” of an incident

• Why incident reviews should produce follow-up work, not just a nicer explanation of what broke

• The difference between finding the cause of an incident and improving the system

• Where AI agents can help with incident investigation, telemetry, metrics, and query building

• Why AI-generated code can increase change volume while reducing human context

• How faster code generation changes the kinds of reliability problems teams should expect

• Why recovery practice matters, especially for region loss, traffic spikes, overload, and restart behavior

• What smaller DevOps and SRE teams can learn from Meta-scale reliability patterns

• Why not every system needs six nines, especially early in a product lifecycle

• How to think about reliability investment based on user promise, product maturity, and operational risk

• Why At Scale Systems & Reliability is focused on the infrastructure behind AI and the use of AI to operate large-scale systems

Francois’ links

• LinkedIn: https://www.linkedin.com/in/francoisrichard/

At Scale links

• Systems & Reliability 2026: https://bit.ly/4xd2FdG

• At Scale Conferences: https://atscaleconference.com/

Our links

More episodes + show notes + links: https://shipitweekly.fm

On Call Brief: https://oncallbrief.com


For anyone building or running modern systems, the sheer volume of news, tools, and incident reports can be overwhelming. Ship It Weekly cuts through that noise. This isn't a surface-level scan of headlines. Host Brian Teller digs into the latest significant outages, major software releases, and insightful post-mortems, focusing squarely on the practical implications for DevOps, SRE, and platform engineering work. Each episode of the podcast breaks down a couple of key stories, providing the crucial context often missing from tech news. You'll hear analysis that translates events into actionable insights, answering the "so what?" for your own infrastructure and processes. The show also includes a quick rundown of tools or updates actually worth your attention, saving you hours of browsing. The tone is direct and informed, favoring depth over breadth. It’s designed for engineers and technical leaders who need a concise, reliable filter for the week's most relevant developments. Listen to this podcast for a focused recap that prioritizes what actually matters, delivered without fluff. You get the news, plus the necessary interpretation to understand how it might affect your systems, your team, and your on-call rotation. It's a weekly briefing that respects your time while aiming to make you more effective.
Author: Language: English Episodes: 50

Ship It Weekly - DevOps, SRE, Platform and Cloud Engineering News
Podcast Episodes
GitHub Outage, PleaseFix Agentic Browser Vulnerability, AWS Certificate Manager Drops Email Validation, Cloudflare TypeScript CI Workflows, AI Observability Consolidation, and the Hidden Cost of “Simple” Platform Changes [not-audio_url] [/not-audio_url]

Duration: 17:39
This week on Ship It Weekly: GitHub suffers another widespread outage affecting the web interface, APIs, Actions, authentication, Copilot, and other critical developer workflows. Zenity Labs demonstrates PleaseFix attack…